
We handed Jev four attachments from a fictional ERP consultancy's shared inbox, and it named the file type correctly on all four. Two were sales documents, a request for proposal and a purchase order. The other two belonged with support, a screenshot of a sync error and a phone photo of a machine nameplate, and Jev kept the pairs apart.
Jev is TypeSafe AI's decision model. It answers narrow questions with numbers your code can act on, instead of writing text. Image reading arrived in preview with the Jev 1.14 release in October, so we ran that test. We've also been testing Jev on our own marketing work since September, and we log every run, including the ones where we overruled it.
You can step through the same inbox example, and seven text examples, in our interactive Jev walkthrough for B2B marketing.
Key points
- Jev returns typed answers. A Noul is the probability that a statement is true and a Choice picks from options you define. A Score places something on a scale, and since 1.14 a Box marks where something sits in an image.
- With the 1.14 release on October 14, 2026, Jev 1.13 and 1.14 both read PNG and JPEG images behind an opt-in header. TypeSafe says image features aren't ready for production yet.
- In our inbox test, every file type came back at 1.00. The box around the purchase order number was right at 0.76 confidence and the box for the RFP number missed at 0.38.
- On text work, Jev's answers matched calls we'd recorded beforehand on 20 of 25 trade show exhibitors and on 24 of 25 companies in an audience list.
- We're also testing it on landing page copy. Two smaller pilots cover source picks for articles and routing work to the right procedure.
- Jev only scores the questions you write. When we left out a question about how current a source was, nothing in its answers pointed to the problem.
What is TypeSafe Jev, and how does it differ from an LLM?
Jev is TypeSafe AI's first "System One" model. You send it the material to judge, which TypeSafe calls the state, along with typed questions. Each answer comes back in a fixed shape that code can use without parsing.
A large language model writes. Jev picks between options you've defined, or tells you how likely something is.
Deciding which of four source passages fits your buyer is a Jev question, and so is checking whether a headline implies a service you don't sell. Writing the headline is still a job for an LLM or a person.
Where typed answers beat generated text
Ask an LLM which of five sources is most relevant to safety buyers and you'll get a persuasive paragraph that someone then has to read. Jev returns a probability for each source. Your code can route on that directly, for example by sending anything under 0.7 to a person, and you can log the numbers next to what your team picked.
TypeSafe doesn't promise the same answer on every call. Answers behind an alias such as jev-latest can shift when a new version ships, so pin a version (jev-1.13.0 or jev-1.14.0) if you plan to compare results across weeks, and log the inputs with each answer.
What changed in Jev 1.14
TypeSafe released jev-1.14.0 on October 14, 2026 and pointed jev-latest at it. The details below come from TypeSafe's changelog and its image docs.
Image input (preview)
Images work on both 1.13 and 1.14 once a request sets the TypeSafe-Danger-Zone-Images header to true. Without that header, an image request fails. An image can go in the material being judged or inside one question. The options themselves can carry images too.
Jev takes PNG and JPEG files up to 16 MiB, with each side between 280 and 1,568 pixels. It won't resize an image that falls outside those limits, so the whole request fails. WebP files need converting first, and so do GIF and HEIC. Images are billed as ordinary input tokens at the usual $0.042 per million, with no separate image charge.
The Box question
Box questions ask where something is. Jev returns one rectangle, given as fractions of the image's width and height, along with a confidence number. Box only runs on 1.14.
A Box always returns a rectangle, even when the thing you asked about isn't in the picture. TypeSafe's docs say to ask a yes/no presence question in the same request and to ignore the box when that answer comes back low.
Longer inputs
Requests normally carry up to 64,000 tokens, or 32,000 for any single question. A second opt-in header raises both limits to 262,000.
TypeSafe is direct about readiness. Its release post says, "we think there is still way too much jaggedness for us to vouch for these for production use cases!" It also says "all models (Jev included) perform worse on multimodality over pure text." So we test image answers on our own files, and nothing that matters runs on them until a person has looked.
What happened when we ran Jev 1.14 on images
On November 5 we ran two small image jobs on jev-1.14.0. Those 9 calls used 28,175 input tokens and cost about a tenth of a cent in total. Each one came back in about half a second.
Sorting a sales inbox
The four attachments were made up for a fictional ERP consultancy called Northline. For each one, Jev answered four questions:
- What kind of file is this: an RFP, a purchase order, a software error or an equipment photo?
- Is it asking Northline to bid on or buy its services?
- Does it show an RFP or PO number?
- Where is that number? (Box)
| Attachment | File type picked | Sales request | Has a reference number | Box confidence | Box on target? |
|---|---|---|---|---|---|
| RFP cover page | RFP (1.00) | 0.85 | 0.98 | 0.38 | No, it sat on the label beside the number |
| Purchase order | Purchase order (1.00) | 0.76 | 0.96 | 0.76 | Yes |
| ERP error screenshot | Software error (1.00) | 0.01 | 0.01 | 0.02 | Nothing to find |
| Equipment nameplate | Equipment photo (1.00) | 0.03 | 0.02 | 0.08 | Nothing to find |
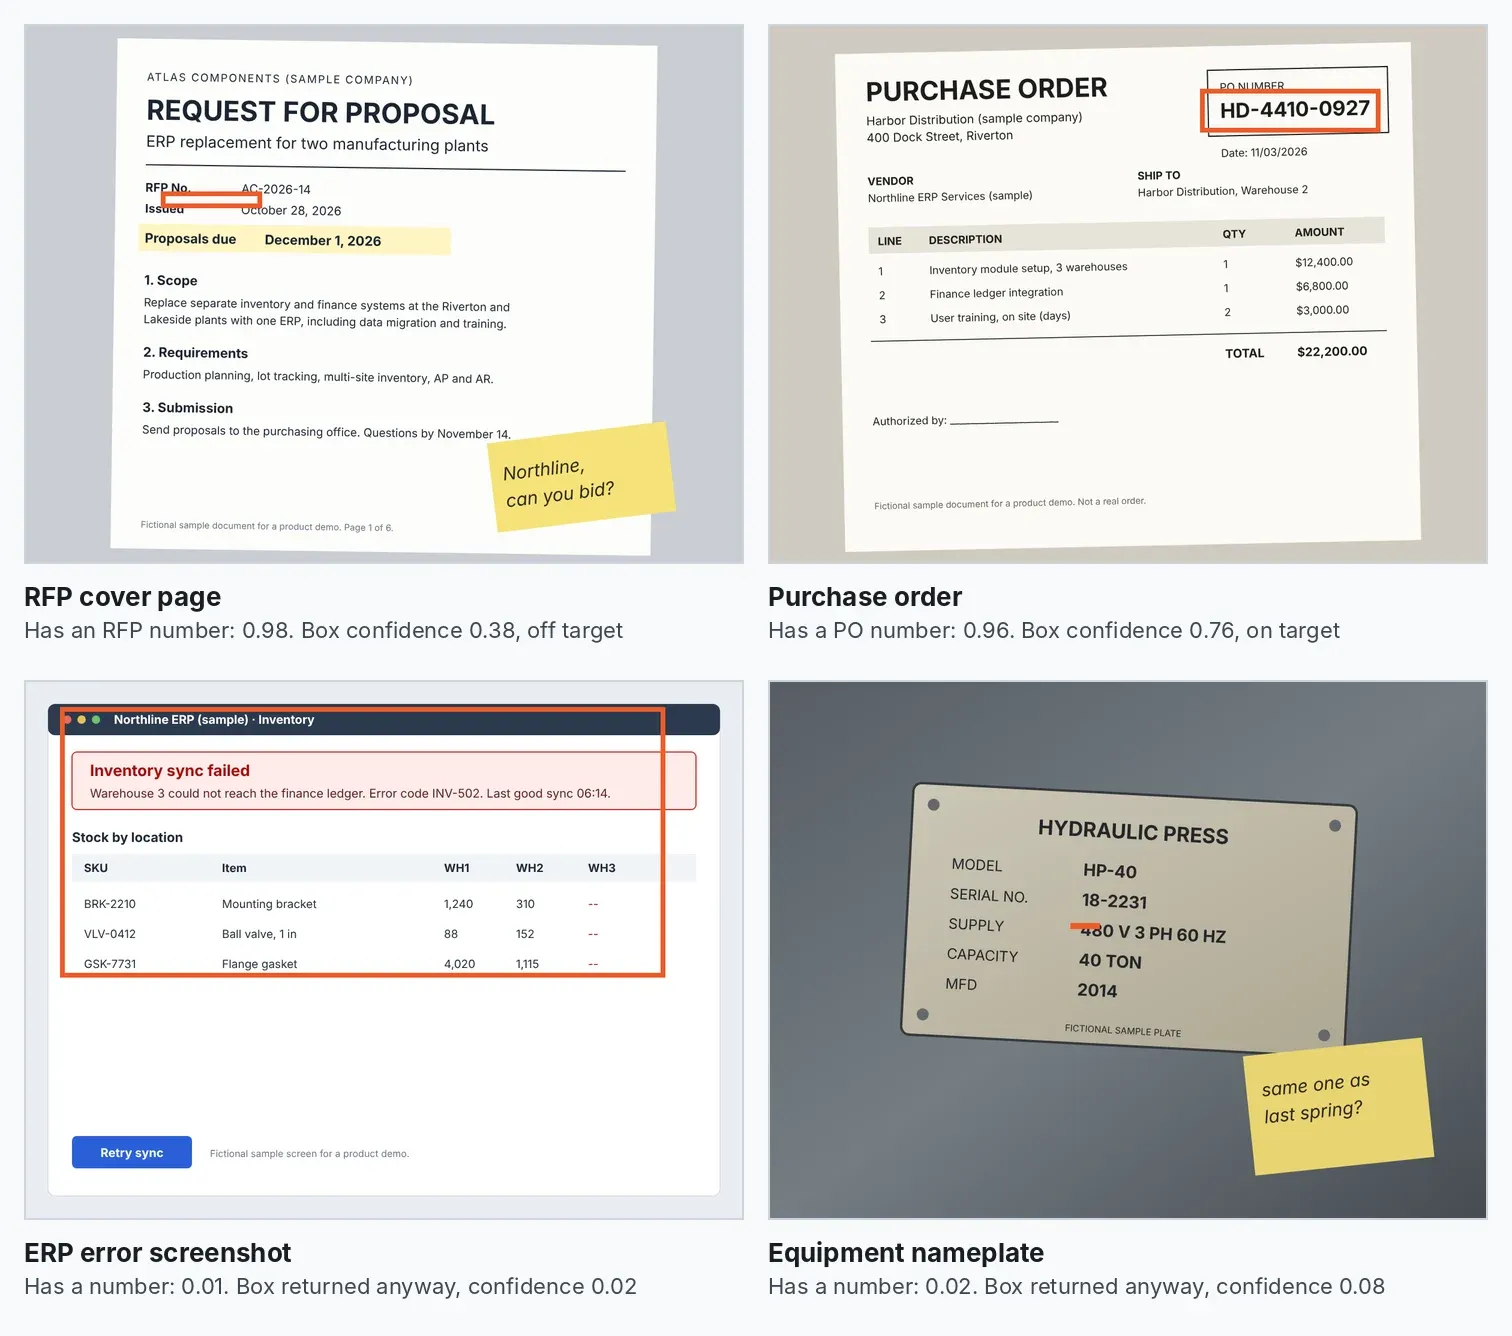
Sorting was the strongest part of the test. The sales-request question put the RFP and the purchase order at 0.85 and 0.76, and the two support files at 0.03 or lower.
Box confidence tracked how good each box was. The one correct box scored 0.76 and the miss scored 0.38. On the screenshot and the nameplate, which had no number at all, Jev still drew boxes, at 0.02 and 0.08, while the presence question read 0.01 and 0.02. A cutoff around 0.5 would have sorted every one of these correctly. That comes from four boxes, so test your own images before you settle on a number.
TypeSafe suggests re-asking a weak box on a closer crop, so we cropped the top of the RFP and asked again. The presence question came back at 1.00. The new box lined up with "AC-2026-14" from side to side but sat a few pixels above it, still at 0.38. Padding the box outward before using it would have caught the number.
Checking our own alt text
The second job looked at the four images this post had before this update, including the poster frame of the demo video. For each one we asked three questions:
- Does the alt text describe what the image shows?
- Does the image show words that the alt text leaves out?
- Does the alt text describe anything that isn't there?
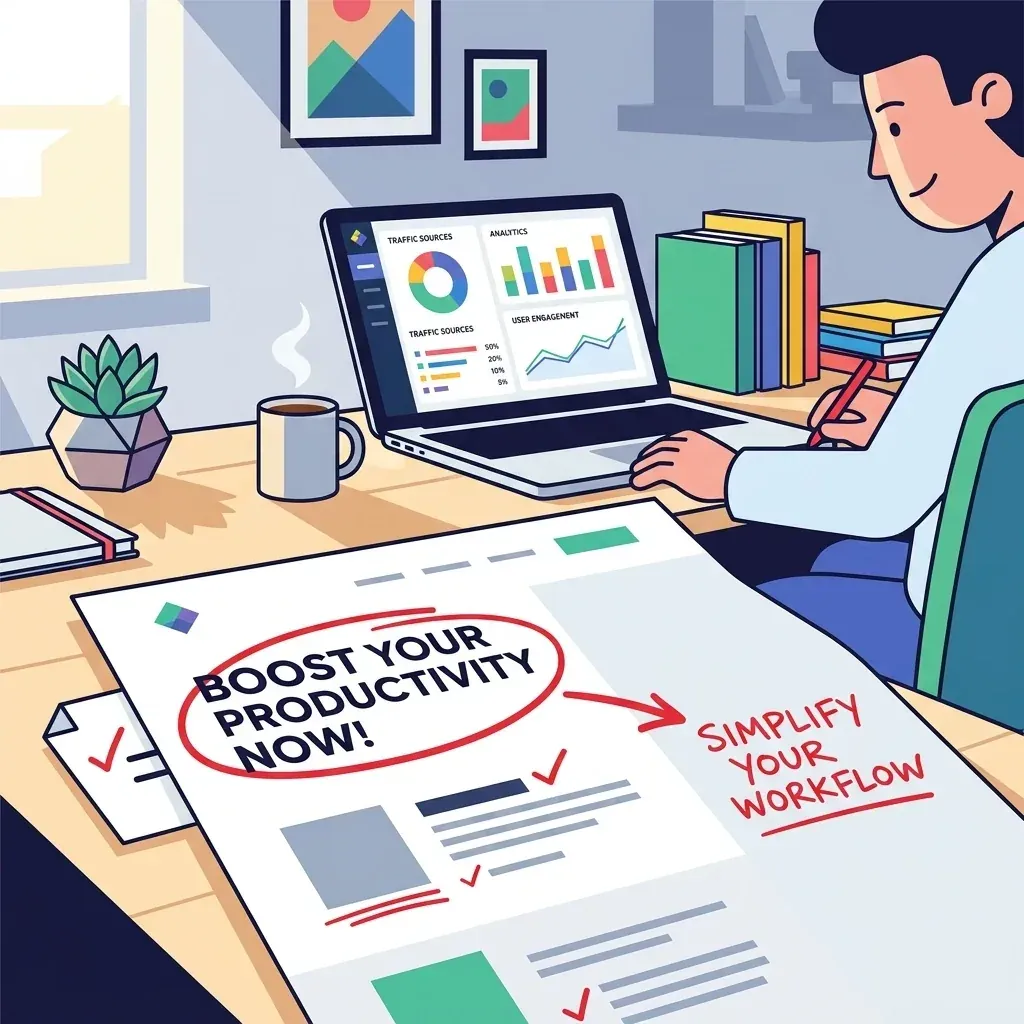
Every alt text scored between 0.88 and 0.92 on the first question, and none was flagged on the third, which stayed between 0.07 and 0.20. The useful flag came from the second. Jev said the landing-page illustration showed words its alt text skipped, at 0.92. It was right. The drawing has "Boost your productivity now!" circled in red and "Simplify your workflow" written beside it, and the alt text mentioned neither. We've fixed that alt text further down this page.
Getting the files ready took more work than the calls did. Our images were WebP, which Jev won't accept, and the header image was 32 pixels too wide. Both had to be fixed first.
Image use cases for industrial vendors
Each of these asks Jev to sort an image or find something in it. Whether a design looks good stays a human call. Treat every one as a suggestion for a person to confirm until TypeSafe calls images ready.
- Inbox attachment triage. Suggest a queue for each RFP, purchase order, drawing and error screenshot, so a rep confirms the routing instead of opening every file. This worked best in our test.
- Reference numbers on scanned documents. Use a Box to point at the PO or RFP number, show high-confidence boxes first, and have a person read the number.
- Required parts on ads and one-pagers. "Does this image show the product?" and "Is the offer printed on it?" are factual checks a person can confirm in seconds.
- A product photo library. Tag images by product line so sales and content teams can find the right picture.
- Trade show photos. Sort them by booth or product before follow-up starts.
- Alt text on your own site. Ask whether each alt text matches its image and whether it skips words that appear in the picture.
How we use Jev on text work
These runs come from our own logs since September. Several map straight onto a vendor's own marketing work, like ranking a trade show list or building a LinkedIn audience. Each had a spending cap. One of our agents or editors reviewed the results before anything was used, and nothing went out without my sign-off.
- Trade show exhibitors. We scored 25 exhibitors on three fit questions each. Jev's priority bands matched a manual ranking saved before the run on 20 of 25, for less than a tenth of a cent. The reviewer still moved two companies down, because their product details came only from a directory listing and their own sites wouldn't load.
- A LinkedIn company audience. Jev helped sort companies from a connection export. We asked it whether each one was B2B and whether it was founder-led, plus a third question that flagged software companies so we could leave them out. On a 25-company check it agreed on 24 with a baseline written before its answers came back. The 25th was one the baseline had already marked for a closer look. At 204 calls and about 18 cents, it's our most expensive run so far.
- A whole-site page audit. We asked whether each of the 115 pages on colonyspark.com had a clear problem and whether it was out of date, then checked 168 pairs of similar pages for near-repeats. That took 283 calls and cost about five cents. Our rule held a page for review whenever any answer sat between 0.3 and 0.7, and it held 100 of the 115. The questions were fine, but that band was too wide to sort anything.
- Resource triage. Jev ranked 230 templates and guides from an outside library in 267 calls, for about ten cents. All seven we ended up adopting were in its top 20. One label it gave, "separate skill" on all 35 finalists, told us nothing, and we ignored it.
- Event follow-up ideas. Jev scored possible follow-ups for panelists after one of our roundtables. It marked a branded mug and a printed issue as noise. Adding one sales line to the end of an audience note moved its "reads as a pitch" probability from 0.27 to 0.76.
- A LinkedIn post. Jev caught a line that read as if the vendors, not their buyers, had the big buying groups. That question scored 0.72, and 0.06 after the rewrite. Our review panels overruled its pick for the opening line.
We've overruled it on plain judgment calls too. It suggested folding two planned articles into one, and our editor kept them apart because one produces a cross-account agenda and the other a single-account plan. When it scored three newsletter topics within 0.03 of each other, from 2.17 to 2.20, the gap was too small to settle anything, so I made the call.
How we're testing Jev on our own work
Besides the runs above, we're testing Jev on three jobs that come up every week. Each one works the same way. Jev gets the material and a short list of narrow questions, and a person makes the call. We log where we agree with it and where we don't.
Landing page copy
We run landing page copy through Jev before it ships, on our own pages and on pages we build for clients. A headline that sounds fine internally can imply a service you don't provide, and a button label can push too hard for risk-averse compliance buyers. These problems are hard to catch in self-review, because you already know what you meant.
Jev gets the page copy and short notes on each buyer, then these questions, one judgment each:
- Does this headline clearly describe the service, or could a buyer misread what's offered?
- Does the language fit a business buyer, or does it sound like a consumer pitch?
- Is any wording generic enough to fit any vendor in this space?
- Does a call to action use pressure that would put off a compliance-minded buyer?
- Does the copy imply a capability the business doesn't have?
For each headline or button option, Jev returns a probability on every question. Anything in the uncertain middle goes to whoever owns the page, and so does the call on a bolder line than these questions favor. We haven't measured conversion against these scores yet. The scores feed the edit in our go-to-market system, and a person still decides.
Source picks for an article
We score every candidate source for an article before choosing one. Writing the questions made us put our criteria on paper:
- Audience relevance: does this source address a problem your buyer cares about?
- Specificity: does it include concrete details?
- Clarity: can a busy buyer get the point in one read?
- Supporting evidence: does it back its claims with data or documented examples?
- Repetition: does it repeat something you've already published?
- Format fit: does it suit the format you're producing?
In our first pilot, Jev's top pick matched our editor's. Its second pick was an older follow-up story that our editorial baseline, written before Jev ran, had already dropped, because it repeated a recent draft and carried old counts. Our repetition question covered the overlap, and Jev read the story as adding detail. None of our questions asked how current a source was, so nothing marked it down for the old counts. The fix is a question about how current each source is.
Routing work to the right procedure
We automate our own go-to-market workflows with people kept in the loop, and that has left us with a growing library of procedures. Picking the right one takes context a new hire doesn't have, so we're testing Jev on that choice.
In the same pilot, Jev got our procedure list and 26 task descriptions. It matched the answers we'd set in advance on all 26. A simple keyword match got 22. That's a small set with labels written by our own agents, so it shows the setup works and says little about everyday traffic.
The pilot also found a gap outside Jev. One task needed a tool we no longer had, and our own code didn't flag it as a blocker. We fixed that check in our code. Jev also treats the descriptions you give it as current, so we keep them up to date and the person doing the work confirms the procedure before following it.
Setting up classification and routing
Jev always picks an option, even when none fits well. TypeSafe's guidance is to pair a Choice with a yes/no question about whether anything fits, which is the same pairing that let us ignore the stray boxes in our inbox test. Send low answers to a person, and set the thresholds in your own code.
Tune those thresholds on your own data. The 0.3 to 0.7 band from our page audit sounded careful and held 100 of 115 pages.
Keep categories few and clearly separate, because overlapping options split the probability until the answer stops being useful. Start with three to five. Jev can sit in front of a CRM or help desk and suggest the call those systems route on, so you can try it without changing platforms.
Where Jev fell short in our tests
The stale follow-up story above is the clearest case of a gap no question covered.
We never tested any of this against buyer behavior. We don't know whether a headline that scores better on these questions converts better, or whether any page we changed performs better.
Jev also can't judge voice. A clarity score says nothing about whether a founder's voice comes through, which matters most for founder-led content where expertise is the differentiator.
On images, the box for the RFP number missed twice. It sat on the label beside the number on the full page and a few pixels above it on the crop, at 0.38 both times.
For brand positioning, pricing pages, new markets and compliance claims, use Jev to surface problems and leave the final call to someone who knows the market and the rules.
A 90-day pilot
In the first two weeks, pick one decision. Source selection was part of our first pilot, and it's the easiest place to start, because the inputs are concrete and you won't need to touch your CMS or CRM. Write your questions, then run them on 10 to 15 passages.
From week three to week six, have your team make its own picks first, without seeing Jev's, and compare. Track how often you agree. Every disagreement deserves a sentence on why, because that's where missing or fuzzy criteria show up.
Add a second use in weeks seven to twelve.
TypeSafe has Python and JavaScript SDKs, so a developer can send material and questions from your existing tools. If your team works in documents and spreadsheets, a manual pilot where you paste in the inputs and record what comes back is fine to start with. Build the full integration once you know the approach works.
If you already track which accounts visit your site and what they read, Jev can work from that data too. "Which content should we show a visitor from a safety equipment company?" is a classification question once you've defined the categories.
Frequently asked questions
What is TypeSafe Jev?
Jev is a model from TypeSafe AI that answers typed questions instead of writing text. It returns yes/no probabilities, picks from options you define, scores on a scale and, since version 1.14, marks where something sits in an image.
What does JEV stand for?
We haven't seen TypeSafe expand it as an acronym. In TypeSafe's docs and in this article, Jev is the model's name.
Can Jev read images?
Yes, in preview. Jev 1.13 and 1.14 accept PNG and JPEG images when a request sets the TypeSafe-Danger-Zone-Images header to true. Each side must be 280 to 1,568 pixels, and each file can be up to 16 MiB. TypeSafe says image results aren't production-ready yet.
What is the Jev Box type?
Box is a question type added in Jev 1.14. It returns one rectangle showing where something is in an image, with a confidence number. It always returns a rectangle, even when the target is missing, so ask a yes/no presence question alongside it and ignore the box when that answer is low.
How much does Jev cost?
TypeSafe lists $0.042 per million input tokens, and output is free. Images are billed as input tokens at the same rate. Our nine image calls used 28,175 tokens and cost about a tenth of a cent.
Does Jev give the same answer every time?
TypeSafe doesn't promise that. Answers behind an alias like jev-latest can change when a new version ships, so pin a specific version and log your inputs if you need to compare results over time.
How do you turn editorial standards into Jev questions?
Start with a small set of clearly separate options that map to real decisions. Add a new one only when your disagreement log shows the same edge case more than once. Style debates stay with people.
What should you log when your team overrides Jev?
Record the input, Jev's answer, your choice and a short reason that names what the questions missed, such as a policy change or a shift in positioning. Those reasons become your next criteria.
Before you wire Jev into anything
In our runs, sorting was Jev's strongest job, and our image calls came back in about half a second for a fraction of a cent. The image features are still in preview, so keep a person on the final call. When you overrule it, log Jev's answer next to your reason.